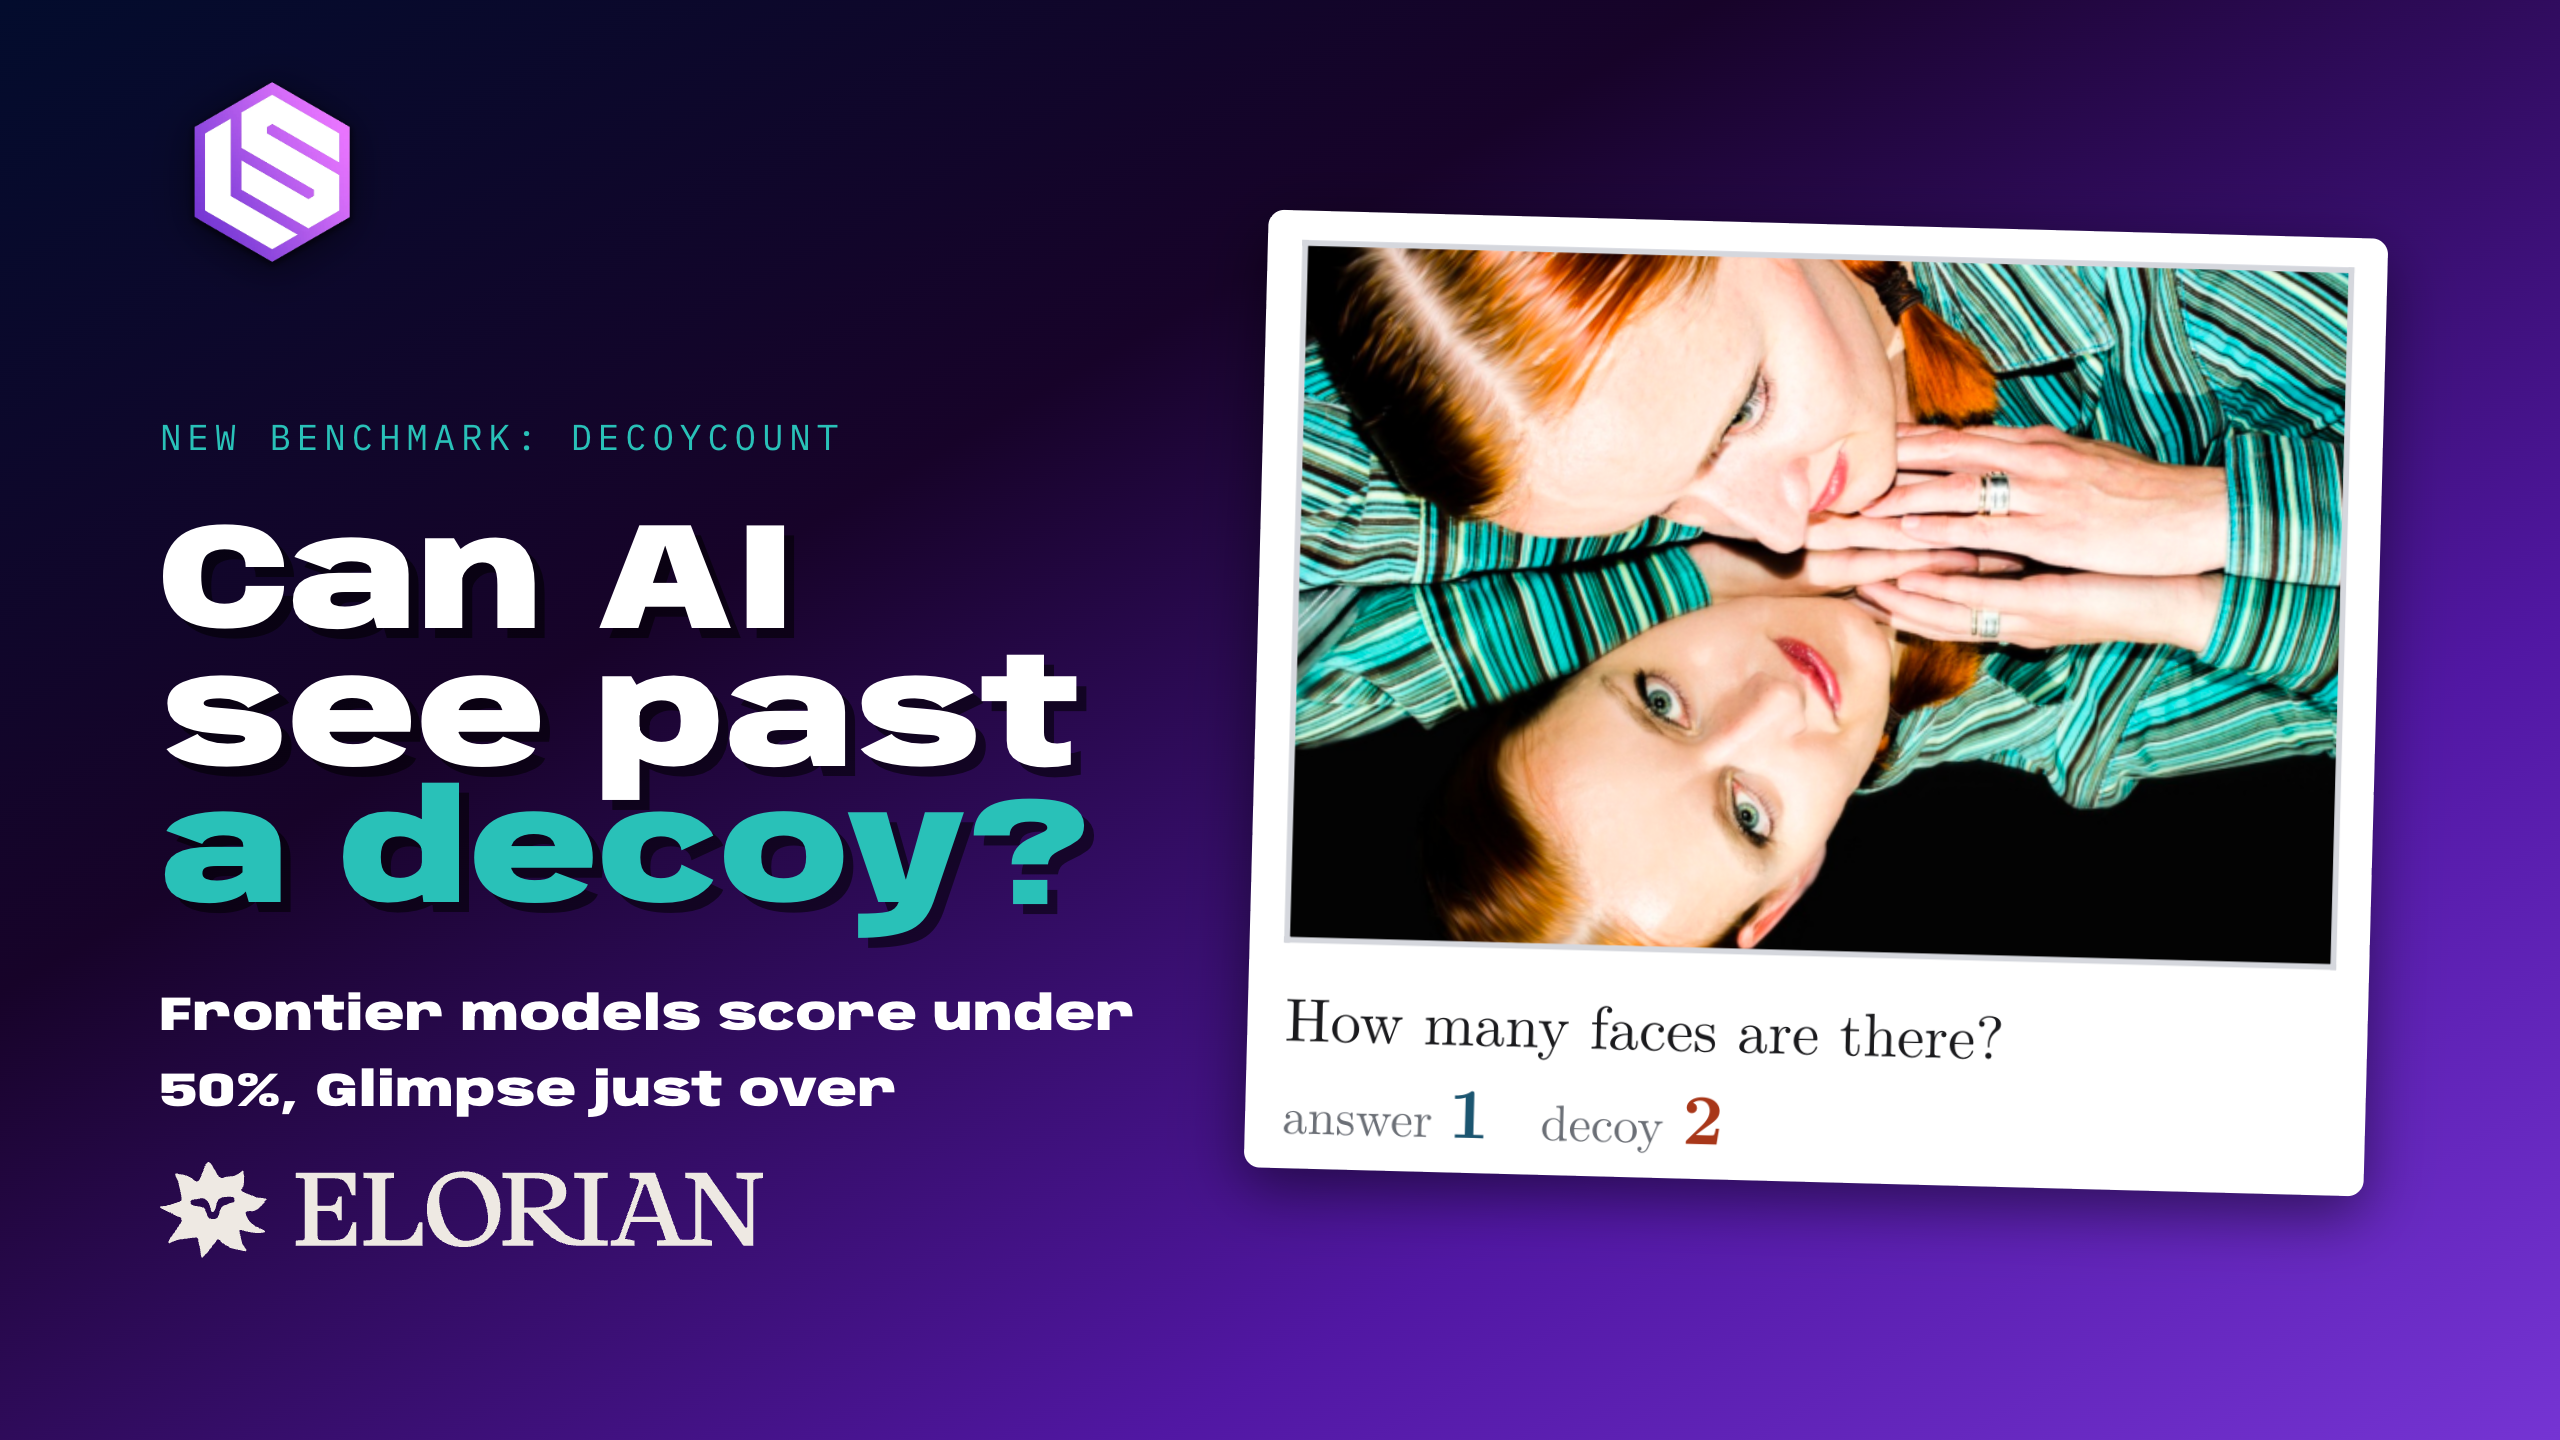
DecoyCount puts frontier models under 50% as Elorian ships Glimpse
Reporting in Latent Space says Elorian shipped Glimpse and the DecoyCount benchmark with Mercor to probe whether multimodal models truly count objects or rely on decoy shortcuts. A release paper referenced there puts frontier contenders below fifty percent, GPT-6 Astra leading at 43.17 percent, while Andrew Dai told the outlet Glimpse scored 50.48 percent on about sixteen hundred sixty items in one internal run kept out of training after Elorian’s contamination check, though that result sits outside the public write-up. The announcement follows Elorian’s April stealth exit backed by fifty-five million dollars in seed funding, relevant for builders weighing vision stacks for physical-world tasks. Treat the leaderboard cautiously because DecoyCount and Glimpse share a sponsor and the reported internal margin remains thin without third-party replication.
DecoyCount puts frontier models under 50% as Elorian ships Glimpse
Elorian co-released DecoyCount with a paper reporting frontier models below 50% accuracy, led by GPT-6 Astra at 43.17%. CEO Andrew Dai told Latent Space Glimpse hit 50.48% on 1,660 items in an internal single-run test withheld from training per their contamination check.
Key takeaway
DecoyCount puts every cited frontier model under chance on visual counting; Glimpse’s narrow internal edge does not by itself validate a new visual-thinking category.
What happened
Latent Space reports that Elorian launched Glimpse, promoted as a visual thinking model that reasons about the physical world from sight, and co-released the DecoyCount benchmark with AI data company Mercor to test genuine object counting versus shortcut heuristics.
According to the accompanying paper cited in that reporting, frontier models scored below fifty percent on DecoyCount, with GPT-6 Astra highest at 43.17 percent. CEO Andrew Dai told Latent Space that Glimpse reached 50.48 percent on 1,660 items in an internal single-run test withheld from training per Elorian’s contamination check; Glimpse is not listed in the public paper.
Evidence
Frontier models scored below 50% on DecoyCount in the release paper, with GPT-6 Astra highest at 43.17%.
Latent Space · attributed
According to the accompanying paper, frontier models scored below 50% accuracy, with GPT-6 Astra highest at 43.17%
Andrew Dai said Glimpse scored 50.48% on 1,660 items in an internal single-run test kept out of training after a contamination check.
Latent Space · attributed
CEO Andrew Dai told Latent Space Glimpse hit 50.48% on 1,660 items in an internal single-run test withheld from training per their contamination check.
DecoyCount was co-released by Elorian with Mercor to test whether models genuinely count objects or use visual shortcuts.
Latent Space · attributed
Elorian launched Glimpse, a visual reasoning model, and co-released the DecoyCount benchmark with Mercor to test whether language models genuinely count objects or use visual shortcuts.
Elorian emerged from stealth in April with $55 million in seed funding before announcing DecoyCount.
Latent Space · attributed
Elorian emerged from stealth in April with $55 million in seed funding , co-led by Striker Venture Partners, Menlo Ventures and Altimeter Capital.
Why it matters
Product and research teams betting on multimodal physical reasoning need independent benchmarks, because vendor-co-released tests can mis-rank capabilities when scores are barely above failing baselines.
Limits and uncertainties
Glimpse’s 50.48% result is an internal, CEO-reported score not included in the public DecoyCount paper and not independently verified in the packet.
The Latent Space material is an excerpt; it does not establish full benchmark methodology, generalization beyond DecoyCount, or third-party replication.
DecoyCount was co-released by the same vendor promoting Glimpse, which the packet flags as a potential conflict-of-interest for interpreting leaderboard gaps.
Practical implications
Treat sub-fifty-percent frontier scores on DecoyCount as a signal to audit vision counting in your own workloads rather than as proof your stack is exempt.
Require external evaluation or hold-out tasks before adopting a visual-reasoning model based on vendor-internal numbers that sit only marginally above the best frontier baseline cited in the paper.